
Diffusers documentation
FreeU
FreeU
FreeU improves image detail by rebalancing how much the UNet decoder draws from backbone features versus skip-connection features. Skip connections can drown out the backbone’s semantic features, which produces unnatural detail in the output. FreeU needs no training, and you can turn it on or off at inference time for text-to-image and text-to-video pipelines.
FreeU only works with UNet-based pipelines like Stable Diffusion, SDXL, and AnimateDiff. It isn’t supported by transformer-based pipelines like Flux or Qwen-Image.
Use the enable_freeu() method on your pipeline and configure the scaling factors. b1 and b2 amplify the backbone features, and s1 and s2 dampen the skip features. The 1 and 2 refer to the first two upsampling stages of the UNet decoder. See the FreeU repository for reference hyperparameters for different models.
Start with the repository values for a model. To tune for other models, keep s1=0.9 and s2=0.2 and adjust b1 and b2 first. Setting all four factors to 1.0 is the same as disabling FreeU. Larger b values strengthen the effect but can oversmooth fine texture, and lowering s1 and s2 counteracts that.
import torch
from diffusers import DiffusionPipeline

pipeline = DiffusionPipeline.from_pretrained(
    "stabilityai/stable-diffusion-xl-base-1.0", dtype=torch.float16,
).to("cuda")  # or "mps", "xpu", "cpu"
pipeline.enable_freeu(s1=0.9, s2=0.2, b1=1.3, b2=1.4)
generator = torch.Generator(device="cpu").manual_seed(13)
prompt = "A squirrel eating a burger"
image = pipeline(prompt, generator=generator).images[0]
image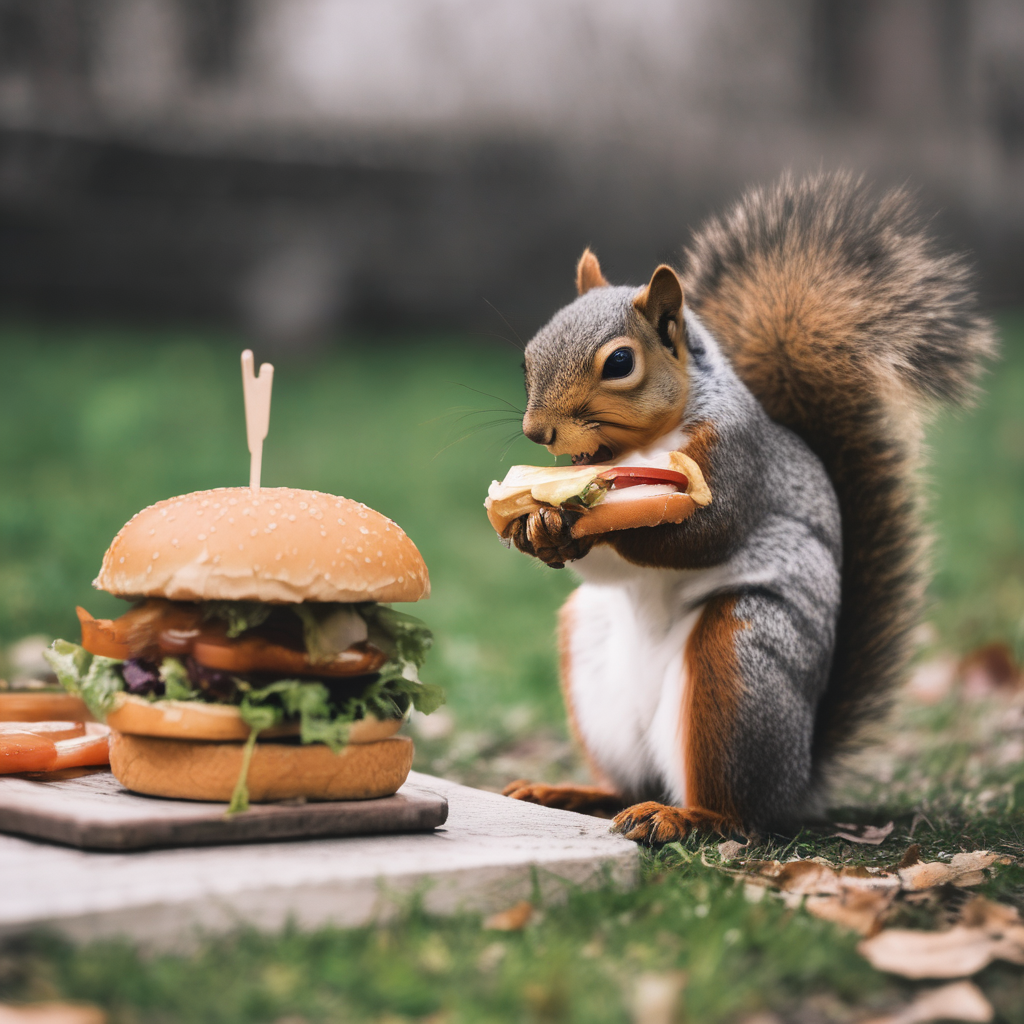

Call the disable_freeu() method to disable FreeU.
pipeline.disable_freeu()
Next steps
- See the enable_freeu() API reference for the full parameter descriptions.
- Try FreeU on video with AnimateDiff.